 RePerspective Labs
INSIGHT
Executive Framework
Self-Healing Enterprise: A New Operating Model
Designing recovery that protects business outcomes, preserves human authority, and reduces recurring failure.
Executive summary
An operation can recover quickly and remain fragile. Automated fixes may restore workflow activity while leaving customer impact, control failures, and recurring causes unresolved. A self-healing operating model should connect three obligations: restore the intended business outcome, keep corrective action within explicit authority, and use the evidence to reduce future disruption. That requires coordinated ownership across operations, technology, knowledge, and controls. Leaders should fund this capability around a specific service and failure pattern, then expand it only when recovery is verified and recurrence or impact improves. The value lies in dependable operations and less avoidable human effort; the number of automated resolutions is an incomplete measure.
The question
If the system is back, has the business recovered?
A workflow restarts. The exception queue clears. The incident is marked resolved. Yet a customer may still be waiting, a reconciliation may still be incomplete, or another team may have inherited the problem.
This is the tension behind self-healing operations: the point at which a technical intervention succeeds may differ from the point at which the enterprise has fulfilled its obligation.
A second gap appears afterward. If the same failure returns, faster recovery can make its underlying cause easier to tolerate. An efficient workaround can become permanent, and the people absorbing the remaining friction can disappear from the performance picture.
The executive question is therefore precise: what must the operating model do to restore a business outcome safely—and make the next disruption less damaging?
My perspective
I would give teams and systems explicit authority to restore a known operating condition, while retaining separate approval for changes to the rules. That allows fast response without letting incident pressure redefine acceptable behavior. Self-healing earns its name when verified recovery leads to a demonstrably less fragile operation.
Shashi Sethi
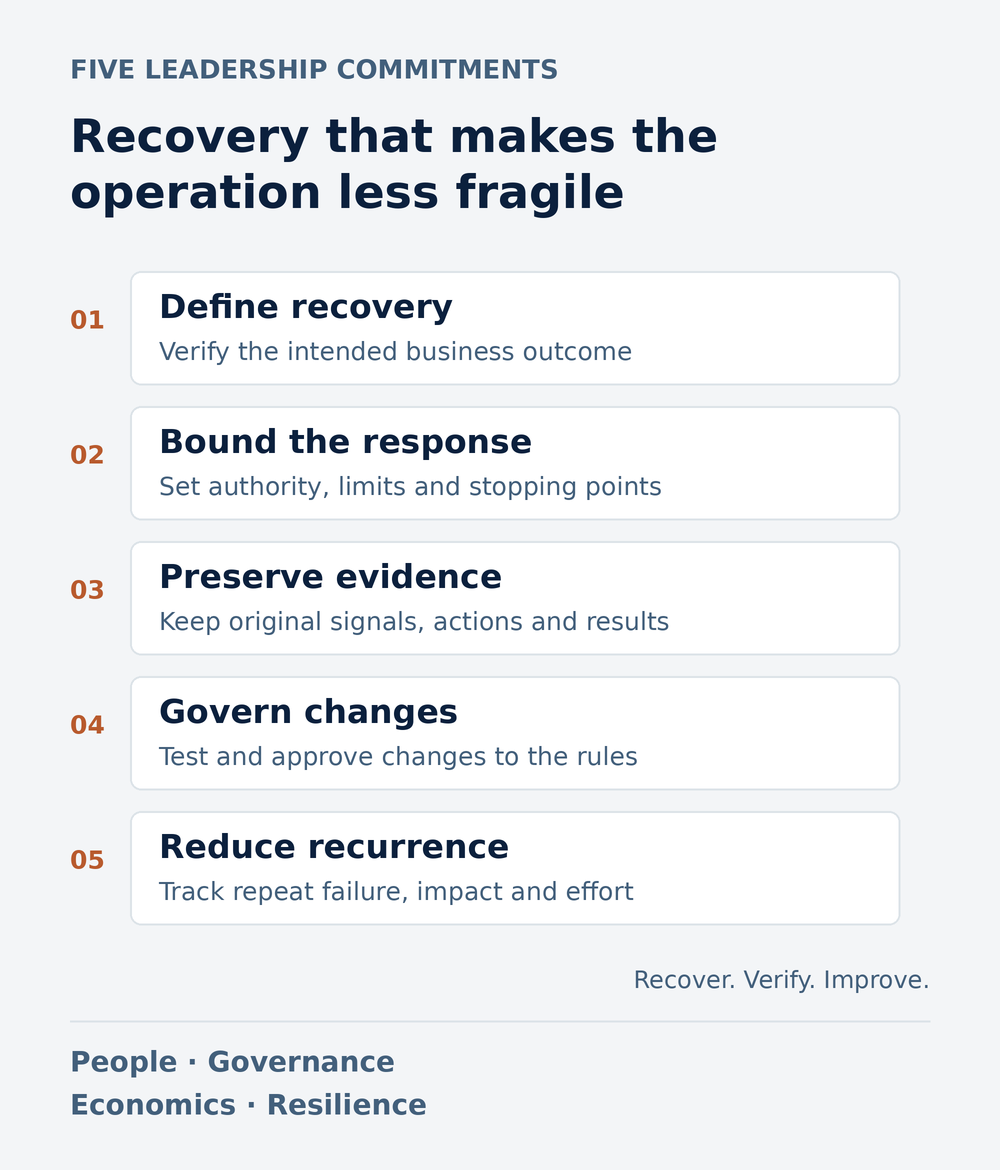
Self-healing connects verified business recovery with bounded action, retained evidence, governed change, and reduced recurrence.
The approach
Define recovery around the business promise
Start with the obligation the operation exists to fulfill: reconcile a payment accurately, make a service available, or complete a customer request within an agreed time. Define the evidence that would establish recovery, including any backlog, downstream checks, and outstanding commitments.
This perspective has an established foundation. The Basel Committee’s Principles for Operational Resilience, published on 31 March 2021, centers resilience on banks’ ability to deliver critical operations through disruption and calls for mapping their dependencies. Its scope is banking; the broader operating lesson I draw is to define recovery around the service and the relationships supporting it. BCBS: Principles for Operational Resilience.
For a self-healing capability, that means agreeing in advance what counts as restored, what degradation is temporarily acceptable, and who can accept the remaining exposure. An application reporting normal status cannot settle those business questions.
Self-healing builds on incident management, continuity planning, and continuous improvement. Its contribution is to connect them inside the flow of work: a signal leads to a governed response, the outcome is checked, and the evidence becomes available for improvement.
Give every recovery action a stopping point
A familiar symptom does not establish a familiar cause. Before executing an approved response, the operation needs current context: affected work, source information, dependencies, applicable instructions, and the limits of its authority.
Use AI assistance where it has been evaluated for a defined task, such as assembling incident context or proposing a diagnosis. Keep the proposed explanation distinguishable from verified facts. For a stable, well-understood response, a tested rule may be sufficient. A confidence score alone does not establish that an action is authorized or safe.
The existing Signal-to-Action Decision Matrix remains useful when the conditions for stopping are made explicit:
| Situation | Appropriate response | Boundary or stopping condition |
|---|---|---|
| Known failure; approved response; required conditions verified | Execute the bounded response and check the business outcome. | Stop when an action, time, or attempt limit is reached. |
| Familiar symptom, but changed or incomplete context | Assemble evidence and recommend a response for review. | Do not reuse an earlier approval without confirming that its conditions still apply. |
| Ambiguous cause or potentially serious consequence | Contain the issue where authorized and escalate to the accountable person. | Protect essential service; do not improvise a consequential correction. |
| Corrective action completes, but recovery is unverified or deterioration continues | Stop further automated attempts and activate the defined fallback. | Escalate with the action history and unresolved impact. |
| The same friction recurs or appears across workflows | Retain safe containment while assigning a problem investigation. | Give redesign its own owner and change decision. |
Stopping is part of recovery design. Google’s SRE chapter on cascading failures explains how automatic retries can increase overload and recommends limits on retries, including across service layers. The enterprise implication is that locally reasonable responses need coordination when they share a dependency. Google SRE: Addressing Cascading Failures, 2016.
Define who can suspend those responses together. A rehearsed fallback may preserve a reduced service, hold affected work for review, or move it to a staffed manual path. It must remain usable when the primary capability is impaired.
Separate restoring service from changing the rules
Permission to apply an approved recovery procedure should have a defined scope. It should not silently expand into permission to change policy, relax a control, alter a financial record, or rewrite the procedure itself.
Consider an operation that repeatedly breaches a threshold. Raising the threshold could make the alerts disappear while leaving the underlying exposure unchanged. The recovery mechanism should not be able to redefine success simply because the current definition is inconvenient.
NIST’s AI Risk Management Framework 1.0 includes post-deployment monitoring, override, recovery, and change management in MANAGE 4.1; MANAGE 2.4 addresses responsibilities for disengaging or deactivating systems whose outcomes conflict with intended use. These provisions support managing AI through its operating life. The separation of recovery authority and change authority proposed here is a RePerspective Labs design judgment. NIST: AI RMF 1.0, January 2023.
Make recovery verification trustworthy as well. For consequential actions, check authoritative business records or an independently maintained control instead of relying solely on the correcting component’s report of success. Preserve the original signal, the action taken, and the result. Changes to the approved response should follow proportionate testing and approval before they become available for future incidents.
A reconciliation break, redesigned
Hypothetical example: the following describes a proposed operating design, not an actual implementation or measured result.
A finance operations team repeatedly encounters payment-reconciliation exceptions when a supplier changes the format of its reference information. Analysts investigate each break, establish the correct relationship, and clear the exception. The next variation creates another investigation.
The business objective is accurate, timely reconciliation with less repetitive investigation. Increasing the apparent matching rate would be insufficient if incorrect matches rose.
In the proposed design, recurring exceptions are grouped with their original records, supplier context, and prior decisions. A newly encountered format goes to an analyst with a suggested explanation. It does not become an automatically accepted format merely because it resembles an earlier case.
Once the relevant owners have validated and approved a normalization rule, it may be applied within its defined scope. Original records remain intact. Amount, currency, supplier identity, and duplicate checks still have to pass. An ambiguous match stays unresolved for human review. The authority granted here does not include releasing payments or changing payee details.
Recovery is confirmed through the agreed reconciliation checks. Meanwhile, the finance Operating owner and supplier relationship owner investigate the source of the variation. They may improve the incoming information, revise the integration, or approve a controlled rule change.
The hypothesis is that this would reduce repeat investigation while preserving accuracy. Test it against comparable volumes and exception types, tracking incorrect matches, aged unresolved items, analyst effort, and downstream corrections. If the queue clears faster but finance absorbs more correction work later, the design has failed its business test.
Give people the capacity to reduce recurrence
The human role needs more definition than “oversight.” Operators need authority to interrupt an unsafe response, access to its evidence, and a clear route to someone who can resolve the underlying business trade-off. The owner of the service must be accountable for the outcome across handoffs.
That responsibility needs time and support. If every released hour is removed from the staffing plan, the people expected to investigate patterns, maintain recovery knowledge, and rehearse fallbacks may have less capacity to do so. Allocate that work explicitly and preserve the skills needed when automation cannot help.
Google’s account of postmortem practice describes reviews that examine contributing causes and action plans without blaming the people involved. This provides a useful foundation for learning from recovery and encouraging people to surface weaknesses. Google SRE: Postmortem Culture, 2016.
Keep the review proportionate. Routine events can feed a pattern analysis; significant harm or repeated failed recovery warrants deeper investigation. Recognize an operator who stops an unsafe action as contributing to service quality.
This also locates the article within the RePerspective Labs canon. Adaptive operations describes the broader ability to adjust as conditions change. Self-healing focuses on recovering from disruption and reducing its recurrence or impact. The Continuous Evolution Loop is the improvement mechanism within that operating model. In the Transformation Operating Map, this connects Improve Continuously with the knowledge and decision context developed in Build the Intelligence Layer; persistent failure can return an issue to Frame the Opportunity.
Measure whether the operation is becoming less fragile
Review recovery speed alongside the quality and cost of the outcome. For the chosen failure pattern, track time to verified business recovery, recurrence relative to workload, incorrect corrective actions, downstream rework, and human intervention effort. Include failures that required fallback; a recovery rate calculated only from easy cases will conceal the boundary of the capability.
A shorter recovery time with unchanged recurrence may justify a useful containment investment. It does not yet demonstrate that the underlying operation has improved. Conversely, reducing recurrence by preventing the problem upstream may be more valuable than expanding automated recovery.
Include the running costs of monitoring, integration, maintaining response procedures, review, and fallback capacity. Time released is capacity; its financial value depends on how the business uses it. Expand authority when the combined evidence supports better service and manageable residual risk.
Leadership takeaway
Review the last three “successful” recoveries
At the next operating review, choose three recurring failures reported as successfully resolved. For each, ask the Outcome owner to show the evidence that the business outcome recovered, what remained for people or downstream teams to complete, and what happened when the approved response was insufficient.
Then follow the evidence forward. Did someone own the recurring cause? Was a change tested? Did recurrence or impact improve over a period that reflects normal workload?
Use the answers to make one investment decision: strengthen a proven recovery path, fund removal of a recurring cause, or narrow automated authority until the fallback is dependable.
The practical commitment is to close the distance between restoring work and improving the conditions under which that work runs.
Sources and further reading
- Basel Committee on Banking Supervision. Principles for Operational Resilience, 31 March 2021. Banking-specific foundation for service continuity, dependency mapping, and learning from incidents.
- Mike Ulrich, Google. Addressing Cascading Failures, in Site Reliability Engineering, 2016. Explains how recovery behavior, including retries, can amplify failure.
- NIST. Artificial Intelligence Risk Management Framework 1.0, January 2023; particularly MANAGE 2.4 and 4.1. Supports lifecycle monitoring, intervention, recovery, and change management.
- John Lunney and Sue Lueder, Google. Postmortem Culture: Learning from Failure, in Site Reliability Engineering, 2016. Describes constructive incident review, action planning, and shared learning.
These sources support particular operating principles. They do not establish measured outcomes for the hypothetical example or validate a complete self-healing enterprise model.